

Maximum of 25 job preferences reached.
Top Senior Site Reliability Engineer Jobs in Boston, MA

Consumer Web • Gaming • Mobile • News + Entertainment • Software
Leads reliability practices across Infrastructure Engineering by defining Service Level Objectives, Service Level Indicators, error budgets, observability standards, and reporting. Partners with engineering teams to connect infrastructure reliability to application and platform outcomes, analyzes distributed-system failure modes, builds Datadog dashboards and monitoring, and influences reliability strategy through technical guidance, mentoring, and executive communication.
Top Skills:
Amazon Web ServicesDatadogDistributed SystemsError BudgetsKubernetesObservabilityService Level IndicatorsService Level ObjectivesSre
Consumer Web • Gaming • Mobile • News + Entertainment • Software
Leads the strategy, architecture, and operation of Kubernetes-based cloud and on-premise infrastructure. Drives reliability engineering, Infrastructure as Code, GitOps, observability, automation, incident response, capacity planning, and cost optimization. Leads cross-functional platform initiatives, establishes SLOs and error budgets, mentors engineers, and advances AI-enabled engineering practices across the organization.
Top Skills:
Amazon Elastic Kubernetes ServiceAWSCi/CdDistributed SystemsGitopsGoGoogle Cloud PlatformGoogle Kubernetes EngineInfrastructure As CodeKubernetesLinuxObservabilityPulumiPythonRke2Terraform

Artificial Intelligence • Information Technology • Consulting
The Linux Systems Administrator will maintain and troubleshoot Linux systems, support network services, and work on systems integration while collaborating with infrastructure teams.
Top Skills:
DhcpDnsLinuxNtpPython

Digital Media • Gaming • Information Technology • Software • Sports • Esports • Big Data Analytics
Lead reliability, scalability, and operational excellence of large-scale database platforms across cloud and on-prem. Build automation-first database infrastructure (Kubernetes operators, IaC, GitOps), drive monitoring/SLOs, incident leadership, performance and cost optimization, and partner with application teams on safe schema/migration practices. Mentor engineers and evaluate AI-assisted workflows to improve productivity and reliability.
Top Skills:
AerospikeArgocdAuroraClaudeCloud SqlCursorDatabase OperatorsEksFluxcdGithub CopilotGitopsGkeGoKubernetesMcpMongoDBMySQLPersistent VolumesPostgresPulumiPythonRedisScylladbStatefulsetsTerraform
2 Months AgoSaved
Easy Apply
Easy Apply
Cloud • Security • Software • Cybersecurity • Automation
Build and operate reliable, scalable production infrastructure for GitLab’s user-facing services. Responsibilities include developing infrastructure automation and tooling, managing Kubernetes deployments, maintaining infrastructure as code, supporting CI/CD and GitOps, participating in on-call and incident response, improving observability and SLOs, troubleshooting production systems, and documenting operational practices. The role spans Intermediate through Senior Staff levels and requires strong software engineering, cloud, reliability, and asynchronous collaboration skills.
Top Skills:
AlertingAWSCi/CdGCPGitopsGoInfrastructure As CodeKubernetesLoggingMetricsRubySlisSlosTerraform

Social Media • Software
Design, implement, and operate infrastructure for high-scale production systems serving millions of users. Own reliability, observability, incident response, deployments, capacity planning, cost management, and operational excellence across bare-metal and cloud environments. Develop automation and performance tooling, improve production readiness, manage vendors, lead incident reviews, and mentor engineers on reliability and distributed-systems practices.
Top Skills:
Bare-Metal ServersCloud ServicesDatabasesDistributed SystemsGoKubernetesLinuxNetworkingObservability SystemsStorage Systems
Artificial Intelligence • Big Data • Healthtech • Software • Biotech
Owns resilience, performance, scalability, and operational cost improvements for a cloud-native platform. Designs and delivers full-stack solutions, builds monitoring and analysis capabilities, performs architectural and code reviews, and resolves complex production issues. The role requires pragmatic modernization judgment, AI-assisted development experience, customer or user accountability, and participation in a weekend on-call rotation.
Top Skills:
Ai-Assisted DevelopmentCloud-Native PlatformsDashboardsFull-Stack Web ApplicationsGrafanaLoggingMonitoring

Other
Build and operate AWS GovCloud environments within FedRAMP boundaries, including multi-account infrastructure, guardrails, logging, security tooling, and Terraform provisioning. Develop automated fleet release, patching, verification, CI/CD, compliance evidence, telemetry, SLO, and alerting systems. Support VM and appliance fleets at scale, participate in on-call, and engineer recurring incident causes away. The role also requires compliance-as-code, continuous monitoring, and test harnesses validating operational state.
Top Skills:
AlertingArtifact ManagementAws ConfigAws GovcloudCi/CdDashboardsFedrampFipsGrafanaKubernetesOpaOpentelemetryOscalSecurity ScanningSlosTelemetryTerraform

Cloud • Security • Cybersecurity
Owns operational capabilities for FedRAMP-regulated cloud environments, including monitoring, alerting, backup and recovery, continuous compliance evidence, incident response, and automation. The role leads major incident command, improves runbooks and operational standards, supports client-facing service delivery, partners on transitions to managed operations, and mentors engineers. Requires deep cloud operations, observability, infrastructure-as-code, resilience engineering, security-control frameworks, and senior escalation experience.
Top Skills:
AnsibleAWSAzureCi/CdGCPGoInfrastructure As CodeJSONOscalPolicy As CodePythonSIEMTerraform

Blockchain • Energy • Cryptocurrency
The Senior Site Reliability Engineer will assess and improve the reliability, scalability, observability, and incident readiness of cloud-hosted applications and distributed systems. Responsibilities include implementing reliability mitigations, establishing performance and capacity testing, building monitoring and automation, creating runbooks, supporting incident response, and coordinating application-specific changes with system owners. The role will also help establish SRE processes, on-call practices, service-level indicators, and safe remediation capabilities.
Top Skills:
AlertingAPIsCachesCapacity TestingChaos TestingCi/CdCloud-Hosted ApplicationsDatabasesDistributed SystemsFlutterHealth ChecksLoad TestingLoggingMetricsObservabilityQueuesScriptingStress TestingTracing
Fintech • Financial Services
Build and govern reliable, scalable production infrastructure across cloud environments. Responsibilities include DevOps guardrails, CI/CD, Terraform-based infrastructure, deployment strategies, developer platforms, observability, SLOs, incident response, capacity planning, automation, chaos engineering, and cloud optimization. The role partners with engineering teams to improve resilience and supports .NET services across Windows and Linux.
Top Skills:
.NetAWSAws App MeshAws Fault Injection SimulatorAws Secrets ManagerBashCdnsCi/CdCloudwatchDatadogDnsDockerEcsElk StackGitopsGoGrafanaGremlinHashicorp VaultIstioLinkerdLinuxLitmusNew RelicPowershellPrometheusPythonTerraformWindows

Artificial Intelligence • Big Data • Healthtech • Biotech • Pharmaceutical
Build and operate reliable cloud infrastructure, developer platforms, CI/CD systems, observability, and production workloads. Support applications, data systems, ML pipelines, and AI workloads across development, staging, and production. Establish SLOs, monitoring, incident response, automation, infrastructure-as-code practices, and operational standards. Collaborate with Product Engineering, Data Engineering, Data Science, and Security while mentoring engineers and participating in support rotations.
Top Skills:
AWSAzureCi/CdDockerGCPGitInfrastructure As CodeKubernetesOpentofuPythonSnowflakeTerraformTerragruntVercelVirtual Networking
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free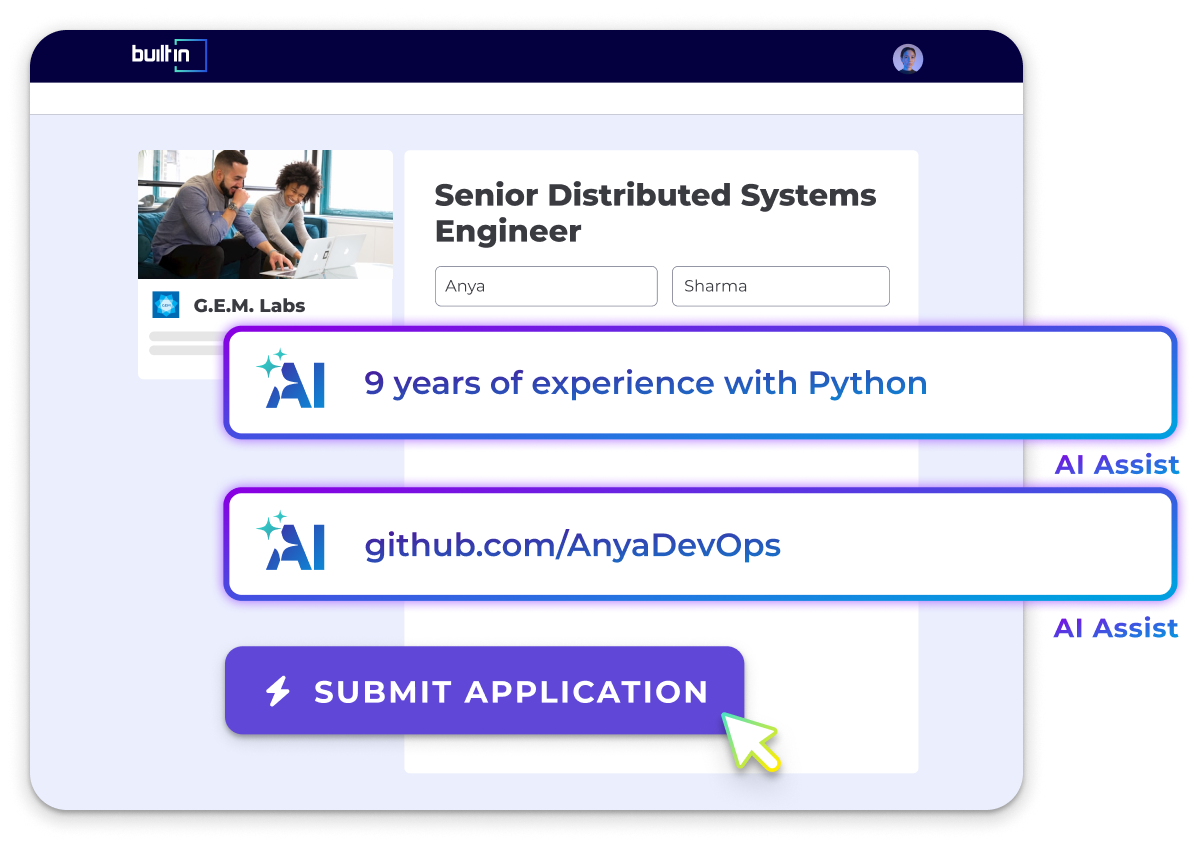

Fintech • Payments
Lead and mentor a global SRE team while overseeing incident response, system health, availability, performance, monitoring, logging, automation, and capacity management. Develop reliability tooling, improve observability, support on-call operations, and partner with engineering and product teams on reliability-focused initiatives. The role also involves project leadership, compliance adherence, and proactive reduction of operational toil through automation and engineering practices.
Top Skills:
AnsibleAWSAzureBashCi/CdCloudFormationDockerElk StackGCPGoGrafanaKubernetesPci-DssPrometheusPythonSoxSplunkTerraform

Artificial Intelligence • Information Technology • Consulting
Lead end-to-end deployment and operation of cloud infrastructure and Symmetri environments for US customers. Provision, configure, monitor, maintain, upgrade, and troubleshoot cloud, single-tenant, on-premises, and air-gapped environments. Manage Kubernetes, networking, IAM, infrastructure as code, resource planning, incident response, runbooks, and root-cause analysis. Represent the company in customer security reviews and help establish US deployment and operations standards and teams.
Top Skills:
AWSAws CdkAzureDnsGitIamKubectlKubernetesLoad BalancingOpentofuPulumiPythonTerraformTerragruntVnetsVpc

Mobile
Serve as Vida’s first dedicated Site Reliability Engineer, modernizing Terraform, standardizing environments, improving CI/CD, scaling GCP and Kubernetes infrastructure, upgrading databases and runtimes, and strengthening monitoring, observability, security, and operational processes. The role includes building runbooks, on-call and escalation procedures, supporting enterprise launches, managing infrastructure costs, and evaluating multi-cluster Kubernetes architecture in a fully remote environment.
Top Skills:
AirflowCloud MonitoringCloud SqlDatadogDjangoFirestoreGCPGithub ActionsGkeIamKubernetesMySQLPostgresPythonRedisTerraform
HR Tech • Payments • Software • Financial Services
Architect, automate, and operate enterprise Akamai CDN, WAF, DNS, edge security, and certificate management platforms. Build Terraform and API-driven infrastructure, self-service capabilities, CI/CD pipelines, and reliability tooling. Establish observability, SLOs, incident response, and performance optimization practices for high-volume internet-facing applications. Partner with application, infrastructure, security, and DevOps teams on secure, scalable, highly available edge services while providing technical leadership and reducing operational toil.
Top Skills:
.NetAkamai ApisAkamai Application & Api ProtectorAkamai Bot ManagerAkamai CdnAkamai Certificate ManagementAkamai Edge DnsAkamai EdgeworkersAkamai Global Traffic ManagementAkamai Property ManagerAkamai Security CenterAkamai WafAWSAzureAzure DevopsC#CachingCi/CdDnsGitGithub ActionsGitopsGoHttp/SJavaScriptJenkinsKubernetesLinuxLoad BalancingPowershellPythonTerraformTlsWindows
Professional Services • Consulting
Own and improve CI/CD, developer tooling, agent harnesses, Kubernetes infrastructure, observability, cost management, and incident-response practices. Build platform capabilities that reduce engineering toil and improve delivery speed for conversational AI products. Participate in an on-call rotation for core infrastructure and help shape reliable, scalable systems across a fully remote engineering organization.
Top Skills:
AlertingCi/CdHelmIncident ManagementKubernetesLlmsLogsMetricsMonitoringNode.jsObservabilityPythonTerraformTracingTypescript
Consumer Web • Gaming • Mobile • News + Entertainment • Software
Own database reliability, scalability, and operational excellence across cloud and on-premises environments. Build automated Kubernetes-based database platforms, infrastructure tooling, failover and backup systems, and self-healing capabilities. Lead observability, performance optimization, capacity planning, incident response, and safe migration practices. Partner with application teams, leverage AI for operational improvements, mentor engineers, influence architecture, and drive technical strategy for highly available database infrastructure.
Top Skills:
AerospikeArgocdAuroraClaudeCloud SqlCursorEksFluxcdGithub CopilotGitopsGkeGoKubernetesKubernetes OperatorsMcpMongoDBMySQLPersistent VolumesPostgresPulumiPythonRedisScylladbStatefulsetsTerraform

Reposted 2 Months AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
As a Senior Site Reliability Engineer, you'll design and build complex systems, support Atlas platform operations, automate processes, and ensure high availability of services.
Top Skills:
AWSAzureDnsGCPGoHTTPLinuxPythonRubyTls
Digital Media • Gaming • Information Technology • Software • Sports • Esports • Big Data Analytics
Leads reliability standards across Infrastructure Engineering by developing Service Level Objectives, Service Level Indicators, error budgets, observability reporting, and reliability measurement practices. Partners with engineering teams to connect infrastructure performance to application and customer experiences, analyzes distributed-system failure modes, and influences teams through technical guidance, mentoring, and communication with senior leadership.
Top Skills:
Amazon Web ServicesDatadogDistributed SystemsKubernetesObservability PlatformsOn-Premise Infrastructure

Cloud • Fintech
Build and operate reliable, scalable cloud applications through automation, infrastructure as code, CI/CD, monitoring, incident response, capacity planning, and SLO management. Collaborate with software engineers on resilient system design, support development environments, improve operational processes, and participate in 24x7 on-call rotation. The role requires expertise with AWS, Kubernetes, Terraform, Docker, networking, and observability, along with mentoring and leadership in SRE practices.
Top Skills:
Amazon CloudwatchAmazon EksAmazon RdsAWSAzureCi/CdDnsDockerDocker DesktopGoGCPHTTPKubernetesmacOSTcp/IpTerraformTypescriptWindows

Healthtech • Software
Owns reliability, availability, incident response, and infrastructure for a regulated SaaS platform. Maintains AWS and Azure environments using Terraform, operates Kubernetes production systems, develops automation, improves observability and deployment safety, mentors engineers, and helps establish the company’s reliability practice.
Top Skills:
AWSAzureBashCloudwatchGrafanaKubernetesPrometheusPythonTerraform
Fintech • Payments
Develop and maintain reliable platforms through automation, observability, incident response, performance optimization, and infrastructure improvements. The role collaborates with engineering teams, supports 24x7 reliability rotations, troubleshoots complex issues across code and infrastructure, and improves operational processes. Required experience includes SRE or equivalent work, software development, cloud platforms, monitoring, databases, and containerization. Preferred skills include Terraform, REST APIs, Grafana, Splunk, Agile, and GitOps.
Top Skills:
AWSAzureC#DockerGCPGitopsGoGrafanaJavaKubernetesNoSQLPythonRdbmsRest ApisSplunkTerraform

Healthtech • Software
Provide technical leadership for site reliability engineering, applying software engineering practices to large-scale operations. Design automated, repeatable operational solutions; monitor service objectives, application performance, and business metrics; improve resiliency, efficiency, and cost. Support cloud and on-premise infrastructure, production applications, deployment automation, testing, and vulnerability response. Partner with software development, security, and business teams while promoting Agile practices, change management, training, and operational health.
Top Skills:
AnsibleAzureCC++ChefDockerEcsGithub CopilotGoJavaKubernetesLinuxPerlPuppetPythonRubyTerraformWindows
Cloud • Security • Software • Cybersecurity
Architect, build, and support reliable network infrastructure and automation for Akamai’s distributed cloud platform. Develop Bash and Python tooling, establish deployment standards, define SLOs, mentor engineers, and troubleshoot complex network issues. The role requires expertise in large-scale distributed systems, TCP/IP, BGP, Linux networking, configuration management, CI/CD, and open-source networking software, with participation in on-call rotations.
Top Skills:
AnsibleArgocdBashBgpBirdChefFirewallsFrrGithub ActionsGoGobgpJenkinsLinux NetworkingLoad BalancingPuppetPythonRustSaltstackSlack BotsTcp/Ip

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Boston Companies Hiring Senior Site Reliability Engineers
See All






Popular Job Searches
All Filters
Total selected ()
No Results
No Results
