

Maximum of 25 job preferences reached.
Top Senior Site Reliability Engineer Jobs in Boston, MA
Artificial Intelligence • Professional Services • Business Intelligence • Consulting • Cybersecurity • Generative AI
Design, develop, deploy, monitor, and maintain AI-enabled enterprise and cloud security solutions. Build machine learning workflows, data pipelines, and scalable security capabilities using Python, Java, TensorFlow, and related libraries. Analyze security risks and data quality, translate technical findings into client recommendations, support security controls across cloud and infrastructure environments, review deliverables, and mentor junior team members.
Top Skills:
Artificial IntelligenceAWSCloud SecurityData PipelinesDatabricksEnterprise SecurityGCPJavaMachine LearningMachine Learning LibrariesAzurePythonSnowflakeTensorFlow
Artificial Intelligence • Professional Services • Business Intelligence • Consulting • Cybersecurity • Generative AI
Leads the design and development of AI-driven enterprise and cloud security solutions. Manages teams delivering data, analytics, and machine learning engineering projects; oversees AI model implementation, data infrastructure, pipelines, and platform deployments. Uses Python and C++ for algorithm development, analyzes data, improves data quality, ensures technical compliance, mentors staff, manages client expectations, and drives innovation across cybersecurity and privacy initiatives.
Top Skills:
AWSC++DatabricksGCPAzurePythonSnowflake
AdTech
Build and maintain cloud-native infrastructure, automate manual operations, develop Terraform modules and Helm charts, manage Kubernetes and service mesh configurations, monitor GCP databases and services, improve observability, maintain CI/CD pipelines, and use AI coding agents to enhance infrastructure development. Collaborate with engineering teams on instrumentation, architecture, capacity planning, scalability, reliability, security, and developer experience.
Top Skills:
Amazon KinesisAWSAws LambdaAws SnsBigQueryClaude CodeCloudsqlCursorDatadogDockerGCPGitlabGoogle Cloud FunctionsGoogle Cloud RunGoogle Pub/SubGrafanaHelmIstioKafkaKubernetesMySQLPrometheusSpannerTerraform

10 Days AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
Build and operate security infrastructure for MongoDB Atlas across AWS, Azure, and Google Cloud. Responsibilities include hardening Linux hosts and containers, implementing cloud security controls, workload identity, vulnerability management, Infrastructure-as-Code, runtime threat detection, and monitoring systems. The role leads initiatives from threat modeling and architecture through deployment and long-term production reliability.
Top Skills:
AnsibleApparmorAWSAzureCC++CgroupsCiliumCloudFormationEbpfFalcoGatekeeperGoGoogle Cloud PlatformKubernetesLinuxMongodb AtlasPythonRbacRustSeccompSelinuxTerraformTetragon

Artificial Intelligence • Cloud • Social Impact • Software • Wearables
Build and maintain the Zero Touch Platform: develop Temporal workflows and Go services to automate cloud operations, own production systems (SLOs, on-call, incidents), debug cloud-native distributed systems, create CI/CD and IaC automation, and produce documentation to enable self-service across engineering teams.
Top Skills:
AksApmAWSAws CloudformationAzureC#Ci/CdEksGoJavaKubernetesLoggingMetricsPythonTemporalTerraform

Fintech • Software
Build and maintain reliable cloud infrastructure, container platforms, automation, observability, and secrets-management systems. Responsibilities include infrastructure-as-code, ChatOps, CI/CD, incident response, on-call support, SLO and SLI management, production troubleshooting, code reviews, and blameless post-mortems. The engineer partners with development, research, and architecture teams to improve system operability, performance, and reliability.
Top Skills:
AiopsAnsibleAWSAws CloudformationAws LambdaAzureChefCursorDockerGithub CopilotGCPGrafanaJenkinsKubernetesLinuxLlmsNode.jsOpentelemetryPackerPagerdutyPrometheusPuppetPythonRancherSaltstackSplunkTerraform
Artificial Intelligence • Cloud • Information Technology • Consulting
Internship SRE role responsible for availability, performance, and scalability of an e-commerce supply-chain platform. Tasks include SLO/SLA definition, observability (Prometheus/Grafana/Loki/Tempo/OpenTelemetry), incident response, capacity planning, disaster recovery for PostgreSQL, infrastructure-as-code (Terraform), CI/CD automation, and operational reliability for AI agent services. Mentored by Head of Technology/CTO with potential conversion to full-time based on performance.
Top Skills:
BashCi/CdDockerGrafanaLangchainLlmLokiMakefileNestjsOpentelemetryOracle CloudPgbackrestPostgresql 15PrometheusPythonRedisTempoTerraformTraefik

Aerospace • Information Technology • Security • Cybersecurity • Defense
Designs and develops Python-based reliability tools and cloud solutions on AWS using Terraform. Builds automation, observability, CI/CD pipelines, and testing frameworks; defines SRE standards, SLIs, SLOs, and error budgets; participates in incident response, on-call support, root-cause analysis, and postmortems. Collaborates across Agile teams to improve platform reliability, reduce toil, optimize cloud costs, and advance cloud-native engineering practices.
Top Skills:
Amazon Ec2Amazon EventbridgeAmazon S3Amazon VpcAWSAws CanaryAws CloudformationAws CloudwatchAws IamAws LambdaAws Step FunctionsCi/CdGoGrafanaInfrastructure As CodePythonTerraform

Fintech • Information Technology • Insurance • Financial Services • Big Data Analytics
Leads architecture, modernization, optimization, and reliability initiatives for mainframe CICS, MQ, and z/OS Connect environments. Provides technical direction across development and operations teams, establishes governance and change processes, tunes performance using telemetry, resolves incidents, and develops modernization roadmaps. Collaborates with stakeholders and enterprise architects to deliver secure, scalable, high-availability solutions while evaluating automation, cloud integration, and AI technologies.
Top Skills:
AnsibleCicsCobolDevOpsIbm MqIbm Z/OsOpenshiftPythonRed Hat Ansible Automation PlatformZ/Os ConnectZlinux

Artificial Intelligence
Staff Site Reliability Engineer responsible for defining reliability and infrastructure strategy, leading complex cross-functional engineering initiatives, architecting scalable AWS and Kubernetes platforms, maintaining Terraform and CI/CD systems, and developing observability practices with SLOs and SLIs. The role mentors engineers, drives operational excellence and infrastructure security, resolves complex production issues, and communicates with technical and executive stakeholders.
Top Skills:
ArgocdAWSCi/CdCoralogixDockerGithub ActionsJavaScriptKubernetesPythonSentryTerraformUnix Shell

Artificial Intelligence • Big Data • Cloud • Information Technology
Own end-to-end client support, troubleshoot production issues, monitor cloud environments, respond to incidents, automate operational tasks, and lead postmortems. Develop and execute manual and automated QA tests, maintain regression suites, integrate testing into CI/CD, and validate AI-powered features. Build documentation, collaborate with engineering and product teams, and improve reliability for regulated-industry clients.
Top Skills:
Ai/LlmAWSAzureAzure MonitorBashCi/CdCloudwatchKubernetesPlaywrightPowershellPythonSQLTerraform
29 Days AgoSaved
Easy Apply
Easy Apply
Cloud • Security • Software • Cybersecurity • Automation
Provide technical direction for GitLab Dedicated, a managed single-tenant SaaS platform. Lead architecture and transformation across resilience, failover, tenant orchestration, change management, automation, and platform integrations. Identify systemic reliability and scalability risks, establish reusable platform patterns, strengthen service ownership, and guide cross-team technical decisions. Mentor senior engineers and advance engineering excellence across the organization.
Top Skills:
Cloud InfrastructureDevsecopsDistributed SystemsGoInfrastructure As CodeObservabilityPythonRuby
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free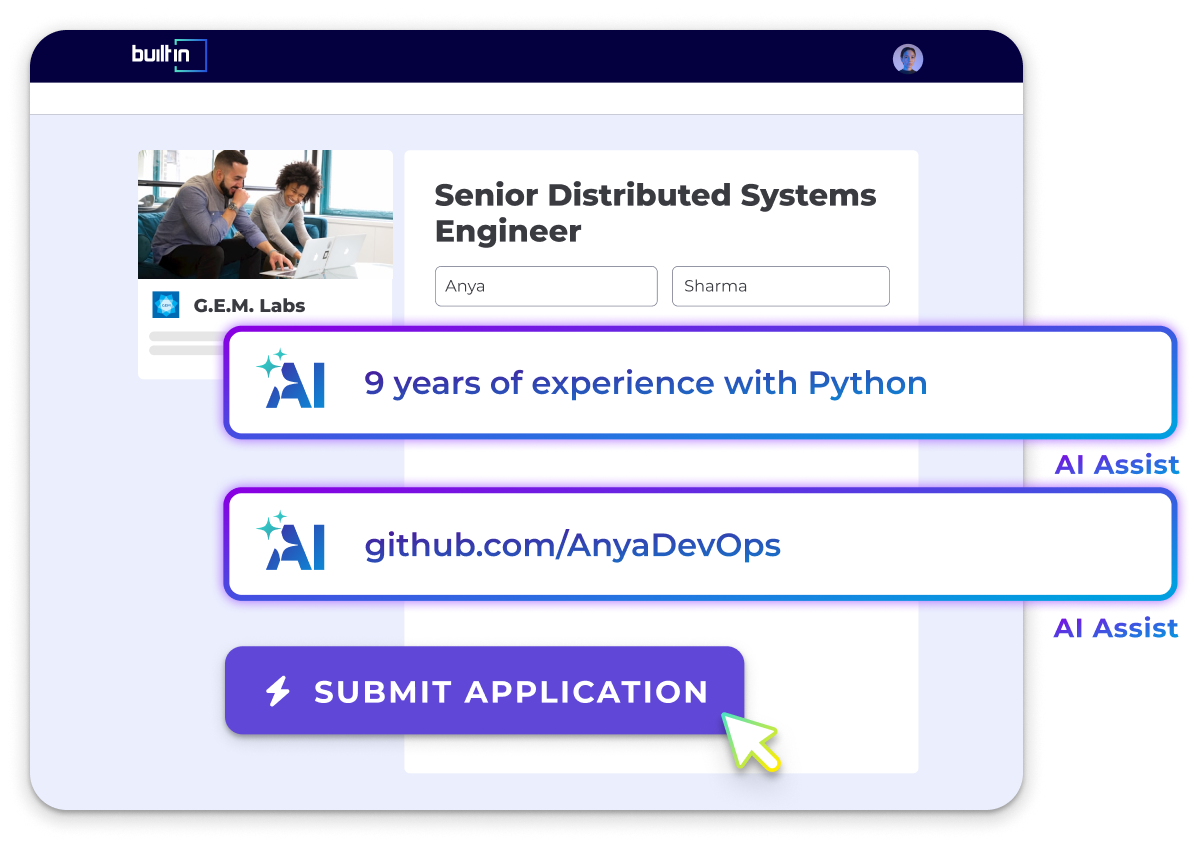
Cloud • Information Technology
Architects, deploys, and operates secure, highly available Kubernetes and cloud infrastructure for AI/ML workloads. Builds Terraform-based automation, GitOps workflows, CI/CD pipelines, observability, and security controls across cloud environments. Serves as a customer-facing technical SME, supporting solution architecture, technical scoping, demonstrations, documentation, and client handoffs. Participates in on-call operations, troubleshooting, root-cause analysis, and post-mortems.
Top Skills:
AWSAws GovcloudAzure GovernmentBashCi/CdCis BenchmarksDatadogDockerFedrampGitopsGoGCPGrafanaKubernetesAzureNistPod SecurityPrometheusPythonRbacSplunkTerraform
Reposted One Month AgoSaved
Artificial Intelligence • Professional Services • Business Intelligence • Consulting • Cybersecurity • Generative AI
Leads teams designing and deploying AI-driven enterprise and cloud security solutions. Responsibilities include developing machine learning systems, integrating data infrastructure and pipelines, performing advanced modeling and analysis, and building AI applications with Python, Java, and C++. The role involves client engagement, strategic problem-solving, stakeholder validation, coaching, process innovation, and operational excellence while addressing complex cybersecurity and privacy challenges.
Top Skills:
Ai SystemsAWSC++Cloud SecurityData EngineeringData PipelinesDatabricksGCPJavaMachine LearningAzurePythonScikit-LearnSnowflakeTensorFlow
Healthtech • Software
Staff Site Reliability Engineer responsible for setting infrastructure direction and owning availability, stability, scalability, observability, disaster recovery, and cloud costs for a SaaS platform. The role involves multi-cloud architecture, managed Kubernetes, infrastructure automation, GitOps delivery, incident response, business continuity, technical evaluations, platform migrations, and mentoring engineers. This is a fully remote U.S.-based position with an on-call rotation.
Top Skills:
Cloud ComputingGitopsInfrastructure As CodeKubernetesObservabilityScripting
Information Technology • Productivity • Software • Manufacturing
Own reliability for production domains across a multi-account AWS SaaS environment. Design observability, alerting, SLOs, automation, Terraform modules, CI/CD pipelines, autoscaling, and self-healing systems. Operate ECS, EKS, Lambda, and PostgreSQL workloads; lead incident response, root-cause analysis, on-call operations, security controls, and compliance automation. Mentor SRE engineers, improve MTTD and MTTR, partner across global teams, and integrate AI into engineering workflows with measurable validation and governance.
Top Skills:
AWSBlue-Green DeploymentCanary DeploymentCi/CdCloudwatchEc2Ecs FargateEksGithub ActionsIamKubernetesLambdaOpenobserveOpentelemetryPagerdutyPythonRds PostgresqlS3TerraformVpc
Healthtech
Lead the evolution of Azure infrastructure toward Kubernetes-based, microservices-oriented systems. Design reliable and scalable cloud infrastructure, observability, networking, CI/CD pipelines, and Infrastructure-as-Code. Drive incident response, cost optimization, capacity planning, performance improvements, and automation while partnering with engineering and data teams. Document best practices, mentor colleagues, and support platform strategy in a healthcare environment with PHI, access control, and audit requirements.
Top Skills:
.NetAWSAzureAzure Entra IdBashC#DatadogGCPGithub ActionsGitlab Ci/CdGrafanaHelmKubernetesPrometheusPythonTerraform

Cloud • Information Technology
Principal Site Reliability Engineer responsible for the availability, scalability, durability, and operational reliability of production systems. The role leads observability, incident response, SLO and error-budget practices, automation, infrastructure as code, and long-term service improvements. Responsibilities include designing monitoring and alerting frameworks, supporting Kubernetes and distributed storage environments, improving operational processes, collaborating across engineering and business teams, and mentoring reliability-focused practices. The position requires extensive experience with Linux, cloud infrastructure, containers, scripting, storage systems, and large-scale production environments.
Top Skills:
AnsibleAWSAzureBashCatchpointDockerElkError BudgetsFirehydrantGCPGoGrafanaHashicorp NomadHashicorp VaultIpvsItilJenkinsKubectlKubernetesLinuxMysqlshPrometheusPythonSlisSlosTerraformVitess
Cloud • Security • Software • Cybersecurity
Performs site reliability engineering for large-scale cloud infrastructure, focusing on application and network performance, reliability, security, scalability, and capacity. Deploys highly available systems, automates cloud service deployments, monitors and troubleshoots services, analyzes logs and events, maintains SLAs, and resolves infrastructure issues. The role requires expertise in microservices, container orchestration, cloud migration, deployment automation, and multiple DevOps technologies.
Top Skills:
AzureChefCloud ComputingContainer OrchestrationGitIntellij IdeaJenkinsKubernetesLinuxMicroservicesMySQLPostgresPythonTerraformVMware
Cloud • Security • Software • Cybersecurity
Analyzes and resolves availability and performance issues in large-scale production and lab environments. Develops automation, monitoring, alerting, log analysis, debugging tools, and systems programming solutions. Collaborates with software development and engineering teams on CI/CD, platform architecture, incident resolution, and operational best practices within an agile SDLC.
Top Skills:
AlertingAnsibleAutomation ScriptingBashContinuous DeliveryContinuous IntegrationDevOpsLinuxLog AnalysisMonitoringPowershellSystems Programming

Digital Media • Gaming • Information Technology • Software • Sports • Esports • Big Data Analytics
Lead long-term strategy and architecture for cloud and on‑prem platform infrastructure, driving Kubernetes and multi‑cloud reliability, IaC/GitOps automation, observability, SLO/SLI/error‑budget practices, incident leadership, AI‑augmented tooling adoption, and mentorship of senior engineers to improve platform resilience and developer experience.
Top Skills:
Amazon Elastic Kubernetes Service (Eks)AutoscalingAWSCapacity PlanningCi/CdGitopsGoGoogle Cloud PlatformGoogle Kubernetes Engine (Gke)Identity And Access ManagementInfrastructure As CodeKubernetesLinuxNetworkingObservabilityOperatorsPulumiPythonRke2StorageTerraform
10 Days AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
Build and operate security infrastructure protecting MongoDB Atlas across AWS, Azure, and GCP. Responsibilities include hardening Linux hosts and containers, implementing Kubernetes security controls, managing CSPM and workload identity platforms, deploying security controls through Terraform and other IaC tools, and creating monitoring and alerting systems. The role leads initiatives from threat modeling and architecture through implementation, rollout, and ongoing production reliability.
Top Skills:
AnsibleApparmorAWSAzureCC++CgroupsCiliumCloudFormationEbpfFalcoGatekeeperGoGoogle Cloud Platform (Gcp)KubernetesLinuxPythonRbacRustSeccompSelinuxTerraformTetragon

Computer Vision • Software
Build and maintain CI/CD pipelines, deployment automation, and cloud infrastructure across Azure and AWS. Manage observability with Datadog or Dynatrace, improve incident response and MTTR, provision infrastructure with Terraform, and develop automation scripts using Python, Bash, or PowerShell. Collaborate across VA engineering programs, improve platform stability, mentor junior engineers, and establish DevOps standards in a remote Agile environment.
Top Skills:
AgileAWSAzureBashCi/CdDatadogDynatraceGithub EnterprisePowershellPythonTerraformVa PlatformVa.Gov

Artificial Intelligence • Healthtech • Software • Telehealth
Design, deploy, and maintain resilient AWS and Kubernetes infrastructure. Build automation, internal tools, CI/CD components, and AI-assisted operational workflows. Establish observability, SLIs, SLOs, and incident-management practices while leading postmortems and reducing toil. Ensure HIPAA compliance, review architecture, identify risks, and mentor engineers on reliability and platform best practices.
Top Skills:
Amazon Ec2Amazon EksAmazon RdsAmazon S3AWSBashDatadogGithub ActionsGoHelmHipaaKubernetesPythonTerraform

Cloud • Software
Support Salesforce GovCloud reliability and high availability in a 24/7 operations environment. Responsibilities include incident response, root cause analysis, infrastructure administration, security and compliance alignment, automation, monitoring, preventative remediation, and workflow improvement. The role requires collaboration across engineering teams, participation in post-incident reviews, and support for AWS/C2S infrastructure and customer-facing services.
Top Skills:
Ai ToolsAWSAws CliAws SdksBambooBsdC2SChefGoJavaJenkinsKubernetesLinuxPuppetPythonRed Hat Enterprise LinuxSolarisSpinnakerTcp/IpUnix

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.






Popular Job Searches
All Filters
Total selected ()
No Results
No Results
