

Maximum of 25 job preferences reached.
Top Remote Senior Site Reliability Engineer Jobs in Boston, MA
Professional Services • Consulting
Own and improve CI/CD, developer tooling, agent harnesses, Kubernetes infrastructure, observability, cost management, and incident-response practices. Build platform capabilities that reduce engineering toil and improve delivery speed for conversational AI products. Participate in an on-call rotation for core infrastructure and help shape reliable, scalable systems across a fully remote engineering organization.
Top Skills:
AlertingCi/CdHelmIncident ManagementKubernetesLlmsLogsMetricsMonitoringNode.jsObservabilityPythonTerraformTracingTypescript

Consumer Web • Gaming • Mobile • News + Entertainment • Software
Own database reliability, scalability, and operational excellence across cloud and on-premises environments. Build automated Kubernetes-based database platforms, infrastructure tooling, failover and backup systems, and self-healing capabilities. Lead observability, performance optimization, capacity planning, incident response, and safe migration practices. Partner with application teams, leverage AI for operational improvements, mentor engineers, influence architecture, and drive technical strategy for highly available database infrastructure.
Top Skills:
AerospikeArgocdAuroraClaudeCloud SqlCursorEksFluxcdGithub CopilotGitopsGkeGoKubernetesKubernetes OperatorsMcpMongoDBMySQLPersistent VolumesPostgresPulumiPythonRedisScylladbStatefulsetsTerraform

Reposted 2 Months AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
As a Senior Site Reliability Engineer, you'll design and build complex systems, support Atlas platform operations, automate processes, and ensure high availability of services.
Top Skills:
AWSAzureDnsGCPGoHTTPLinuxPythonRubyTls

Cloud • Fintech
Build and operate reliable, scalable cloud applications through automation, infrastructure as code, CI/CD, monitoring, incident response, capacity planning, and SLO management. Collaborate with software engineers on resilient system design, support development environments, improve operational processes, and participate in 24x7 on-call rotation. The role requires expertise with AWS, Kubernetes, Terraform, Docker, networking, and observability, along with mentoring and leadership in SRE practices.
Top Skills:
Amazon CloudwatchAmazon EksAmazon RdsAWSAzureCi/CdDnsDockerDocker DesktopGoGCPHTTPKubernetesmacOSTcp/IpTerraformTypescriptWindows

Healthtech • Software
Owns reliability, availability, incident response, and infrastructure for a regulated SaaS platform. Maintains AWS and Azure environments using Terraform, operates Kubernetes production systems, develops automation, improves observability and deployment safety, mentors engineers, and helps establish the company’s reliability practice.
Top Skills:
AWSAzureBashCloudwatchGrafanaKubernetesPrometheusPythonTerraform

Healthtech • Software
Provide technical leadership for site reliability engineering, applying software engineering practices to large-scale operations. Design automated, repeatable operational solutions; monitor service objectives, application performance, and business metrics; improve resiliency, efficiency, and cost. Support cloud and on-premise infrastructure, production applications, deployment automation, testing, and vulnerability response. Partner with software development, security, and business teams while promoting Agile practices, change management, training, and operational health.
Top Skills:
AnsibleAzureCC++ChefDockerEcsGithub CopilotGoJavaKubernetesLinuxPerlPuppetPythonRubyTerraformWindows
Cloud • Security • Software • Cybersecurity
Architect, build, and support reliable network infrastructure and automation for Akamai’s distributed cloud platform. Develop Bash and Python tooling, establish deployment standards, define SLOs, mentor engineers, and troubleshoot complex network issues. The role requires expertise in large-scale distributed systems, TCP/IP, BGP, Linux networking, configuration management, CI/CD, and open-source networking software, with participation in on-call rotations.
Top Skills:
AnsibleArgocdBashBgpBirdChefFirewallsFrrGithub ActionsGoGobgpJenkinsLinux NetworkingLoad BalancingPuppetPythonRustSaltstackSlack BotsTcp/Ip
One Month AgoSaved
Cloud • Security • Software • Cybersecurity
Develop and operate Akamai’s Linux-based cloud infrastructure, including bare-metal and virtual machine platforms, kernels, operating systems, and KVM/QEMU virtualization. Build software, automation, observability, and infrastructure enhancements at scale; troubleshoot complex distributed-system issues; collaborate across engineering and operations; mentor team members; and participate in on-call service restoration.
Top Skills:
AnsibleChefKubernetesKvm/QemuLinuxLinux KernelNested VirtualizationPuppetSaltstack
Artificial Intelligence • Cybersecurity
Own and evolve the company-wide SRE strategy, reliability standards, observability practices, incident management, service ownership, SLOs, and on-call operations. Lead cross-functional reliability initiatives, establish dashboards, alerts, runbooks, and escalation paths, improve production readiness and incident response, and operate large-scale distributed systems across AWS and Kubernetes. Participate in a 24/7 on-call rotation and help shape the SRE function.
Top Skills:
Argo CdAWSDatadogGitlab CiGitopsGrafanaKubernetesNew RelicPythonTerraform

Healthtech • Pharmaceutical
Own the reliability, availability, performance, observability, and security of Ophelia’s GCP telehealth platform. Define SLOs, improve monitoring and incident response, expand Terraform infrastructure, strengthen CI/CD, manage disaster recovery, and address latency and Cloud Run performance. Lead on-call maturity, HIPAA/SOC 2 infrastructure controls, and reliability education for engineers. Use AI-assisted tools for automation and incident triage while partnering with technical and non-technical stakeholders.
Top Skills:
BigQueryClaudeCloud RunFirebaseFirebase AuthenticationFirebase HostingFirestoreGeminiGithub ActionsGoogle Cloud OperationsGoogle Cloud PlatformIamNode.jsPagerdutyPythonReactShell ScriptingSQLTerraformTypescript

Security
Own infrastructure reliability across GCP, Kubernetes, PostgreSQL, and hundreds of cloud projects. Build automation and software that eliminate toil, reduce manual on-call work, address latency and reliability trade-offs, and provide system health visibility. Lead infrastructure projects, define service-level objectives with product teams, improve reliability practices, and develop production systems for agent-first applications.
Top Skills:
GCPKubernetesPostgres

Edtech • Fintech • Information Technology • Software
Operate and improve AWS production infrastructure, infrastructure as code, Kubernetes workloads, observability, CI/CD, and incident response. The role investigates root causes, strengthens application resilience, automates operational tasks, supports database and performance reliability, maintains documentation, and participates in 24/7 on-call rotations. The engineer owns scoped reliability projects and collaborates with product engineering teams on resilient, secure, and compliant systems.
Top Skills:
Amazon EksAmazon RdsAWSCircleCIDatadogGithub ActionsKubernetesLinuxNew RelicOpensearchPostgresRedisRubyRuby On RailsTerraform
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free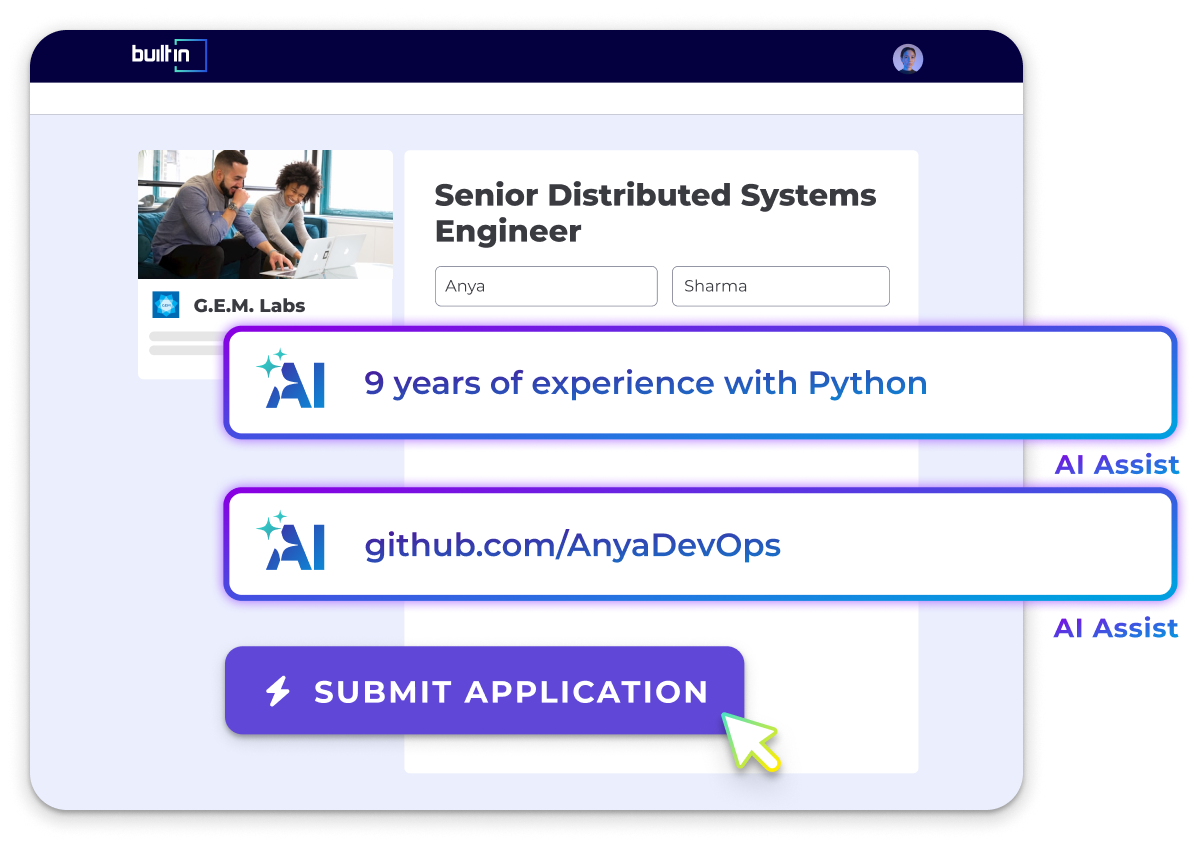
Reposted 3 Months AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
The Senior Site Reliability Engineer will develop and support distributed storage services, ensuring reliability and operational safety, with a focus on automation and efficiency.
Top Skills:
AWSAzureDnsGoGoogle Cloud PlatformKubernetesLinuxPythonTcp/IpTls
Software • Defense
Own reliability, scalability, security, observability, and incident response for production applications across AWS and on-premises DoD environments. Build monitoring and alerting, define SLIs and SLOs, lead post-incident reviews, automate infrastructure with Terraform and Ansible, operate Kubernetes clusters, embed RMF and STIG controls, reduce operational toil, and support secure air-gapped deployments.
Top Skills:
AlloyAnsibleAWSAws GovcloudBashDatadogElk StackGithub ActionsGitlab Ci/CdGitopsGoGrafanaHyper-VIstioJenkinsKubernetesLinkerdLokiNutanixPrometheusProxmoxPythonRmfSecurity+StigsTerraformVMware

Information Technology • Security • Cybersecurity
Own production operations and highly available cloud infrastructure for regulated government environments. Lead incident response, root-cause analysis, disaster recovery testing, compliance operationalization, audit readiness, vulnerability management, and continuous monitoring. Build automation, secure CI/CD pipelines, infrastructure-as-code, observability, and compliance tooling across Kubernetes, Linux, containers, and cloud platforms. Partner with security, compliance, and engineering teams to improve reliability, deployment safety, and regulatory sustainment.
Top Skills:
Aws GovcloudBashCi/CdDod Il4Dod Il5FedrampGitopsGoGrafanaKubernetesLinuxNist 800-53PrometheusPythonStigTerraformUnixZero Trust

Cloud • Software • Analytics
Develop and operate Arista’s FedRAMP CloudVision SaaS platform at scale. Responsibilities include improving reliability, scalability, observability, autoscaling, disaster recovery, capacity planning, CI/CD, network architecture, cost optimization, and cloud application security. The role develops and manages Kubernetes-native services, distributed databases, and automation using technologies such as GCP, GKE, Go, Python, Ansible, Pulumi, and Bash. Participation in a FedRAMP on-call rotation is required.
Top Skills:
AnsibleBashCi/CdDistributed DatabasesFedrampGoGoogle Cloud Platform (Gcp)Google Kubernetes Engine (Gke)KubernetesPulumiPythonSaaS
Legal Tech • Software
Design and improve observability (monitoring, logging, tracing, SLIs/SLOs), build automation and CI/CD, lead incident response and reliability improvements, mentor SREs, run on-call, and apply AI/ML to operational signals to forecast and reduce risks.
Top Skills:
AWSBashCi/CdDistributed TracingGoInfrastructure As CodeKubernetesLoggingMonitoringPythonSlisSlos
Fintech • Real Estate • Software
Lead reliability and observability efforts across the org: design and maintain Kubernetes and AWS infrastructure, build CI/CD pipelines, drive IaC standards (Terraform/Crossplane), partner with 16+ teams to roll out tools and processes, participate in on-call rotation and incident response, and use AI tools to accelerate work.
Top Skills:
Ai ToolsArgoAurora PostgresAWSCi/Cd PipelinesCrossplaneDatadogDocumentdb (Mongo)EcsEksGithub ActionsHelmKubernetesMongoDBPostgresRdsTerraform

Other
Lead platform infrastructure reliability initiatives for a microservices-based cloud SaaS solution. Design scalable, automated, observable infrastructure; define platform roadmaps; guide engineering teams through design reviews; reduce operational toil; build monitoring and alerting; and participate in on-call incident response. The role uses AWS, Kubernetes on EKS, Istio, infrastructure-as-code, GitLab, Argo CD, and Datadog.
Top Skills:
Amazon EksArgo CdAWSAws CdkDatadogEc2GitlabIstioKubernetesRdsS3Terraform

Information Technology • Security • Software • Cybersecurity
Lead reliability strategy across eight engineering groups by defining SLIs, SLOs, and error budgets; strengthening incident response, alerting, postmortems, change safety, and failure testing; and coaching teams to own reliability. The role remains hands-on through production investigations, tooling, dashboards, and reference implementations. It also leads AI adoption in incident management and observability while partnering with architecture, platform, and product teams to improve distributed-system resilience.
Top Skills:
Ai ToolsAWSDatadogDynamoDBElasticsearchGoInfrastructure As CodeKafkaKubernetesObservability ToolingRedisTypescript
Insurance
Designs and operates reliable hybrid application platforms, leading CI/CD, infrastructure automation, cloud resource management, monitoring, security scanning, container orchestration, and database self-service tooling. The role owns the enterprise CI/CD technology stack and hosting strategy across on-premises, hybrid, and cloud environments. It requires extensive collaboration with engineering, infrastructure, security, application, QA, and governance teams, along with 24/7 mission-critical support and technical leadership.
Top Skills:
AnsibleApache CamelAWSCi/CdCloudFormationConfluenceDatabase SystemsDockerGitGithub ActionsGitlab CiGradleHelmInfrastructure As CodeJenkinsJIRAKubernetesLinuxMavenMonitoring And AlertingNetworkingPythonSonatypeTerraformVulnerability Scanning

Cloud • Information Technology • Security • Virtual Reality • Cybersecurity
Support reliability, security, scalability, and performance of the TAK CI/CD pipeline and critical infrastructure. Monitor system health, respond to incidents, patch systems, optimize performance and costs, improve DevOps practices, automate operations, and maintain technical documentation. Requires systems and network administration experience, Linux and cloud expertise, containerization, CI/CD knowledge, Zero Trust implementation experience, Security+ certification, and an active T3 investigation.
Top Skills:
AWSCi/Cd PipelinesContainerizationLinuxZero Trust

Automotive
Design and implement scalable cloud infrastructure, monitor performance, automate processes, ensure security and compliance, and lead a DevOps team.
Top Skills:
AWSBashCi/CdDockerElk StackGCPGrafanaKubernetesPrometheusPythonTerraform

Artificial Intelligence • Big Data • Healthtech • HR Tech • Machine Learning • Software • Big Data Analytics
Own the reliability, performance, resilience, observability, and security of AWS and Kubernetes infrastructure supporting products and AI/ML workloads. Define SLOs, lead incident response and root-cause analysis, build Terraform automation, optimize cloud costs, reduce operational toil, and establish deployment standards that help engineers ship reliably. Participate in on-call rotations and maintain HIPAA-compliant infrastructure.
Top Skills:
AWSClaudeDatadogGitlabGoHipaaIstioKubernetesNatsPostgresPythonSoc 2TerraformTypescript
Information Technology • Legal Tech • Analytics
Build and operate reliable, scalable platforms and services across AWS environments. Responsibilities include infrastructure automation with Terraform, CI/CD development, observability, incident response, disaster recovery testing, AI service deployment, security, infrastructure documentation, and developer enablement. The role partners with engineering teams to improve availability, performance, recovery, and operational self-service.
Top Skills:
Acm/TlsAlbAWSAws CliBashCloudwatchDockerDynamoDBEcrEcsFargateGitGithub ActionsIamKmsLambdaLinuxOidcPythonRdsRoute53S3Secrets ManagerSqsTerraformVpc

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Boston, MA Companies Hiring Remote Senior Site Reliability Engineers
See All






Popular Job Searches
All Filters
Total selected ()
No Results
No Results
